Disease Prediction Using Machine Learning
by: Tomás Ospina.
Overview
A supervised-learning study that predicts a disease from a set of reported symptoms, combining three classifiers into a majority vote rather than trusting any one of them.
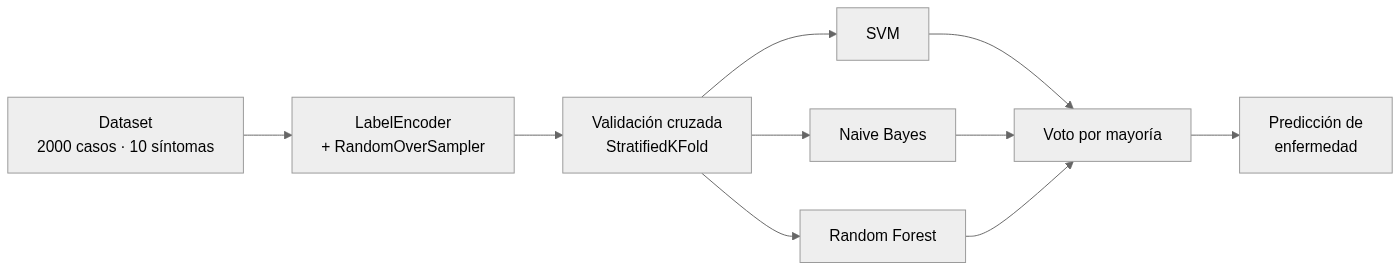
Dataset & Preprocessing
2,000 records with ten binary symptom features — fever, headache, nausea, vomiting, fatigue, joint pain, skin rash, cough, weight loss and yellow eyes — and the diagnosed disease as the target.
Two preprocessing steps do most of the work: a LabelEncoder on the target, and a
RandomOverSampler to correct the class imbalance, since the rarer diseases would
otherwise be predicted away entirely by a model optimising raw accuracy.
Modelling
Three classifiers are trained and validated independently with StratifiedKFold cross-validation — keeping the class distribution intact in every fold — and their predictions are combined by majority vote:
| Model | Role in the ensemble |
|---|---|
SVM (SVC) |
Margin-based separation of the symptom space |
| Gaussian Naive Bayes | Fast probabilistic baseline over the features |
| Random Forest | Non-linear feature interactions, robust to noise |
Results are read off a confusion matrix per model plus the ensemble, so a disease that one classifier consistently confuses is visible rather than buried in an accuracy number.
What I Learned
The oversampling step changed the results more than the model choice did. On an imbalanced medical dataset, a high accuracy score usually means the model has learned to ignore the rare classes — which is exactly the failure mode that matters here.
🔒 Private repository — happy to walk through the code on request.